
Erden
Overview
Erden is a platform for building, publishing, and checking evidence-backed ontologies.
The short version: an ontology should be something you can version, publish, depend on, and verify, the same way you already do with code. Today it usually isn't. It's a diagram somebody made in a workshop, or a spreadsheet, or a graph database nobody has the authority to change. There's no release, no dependency edge, no provenance, and no way for a downstream consumer to check that what they pulled is what the publisher actually signed.
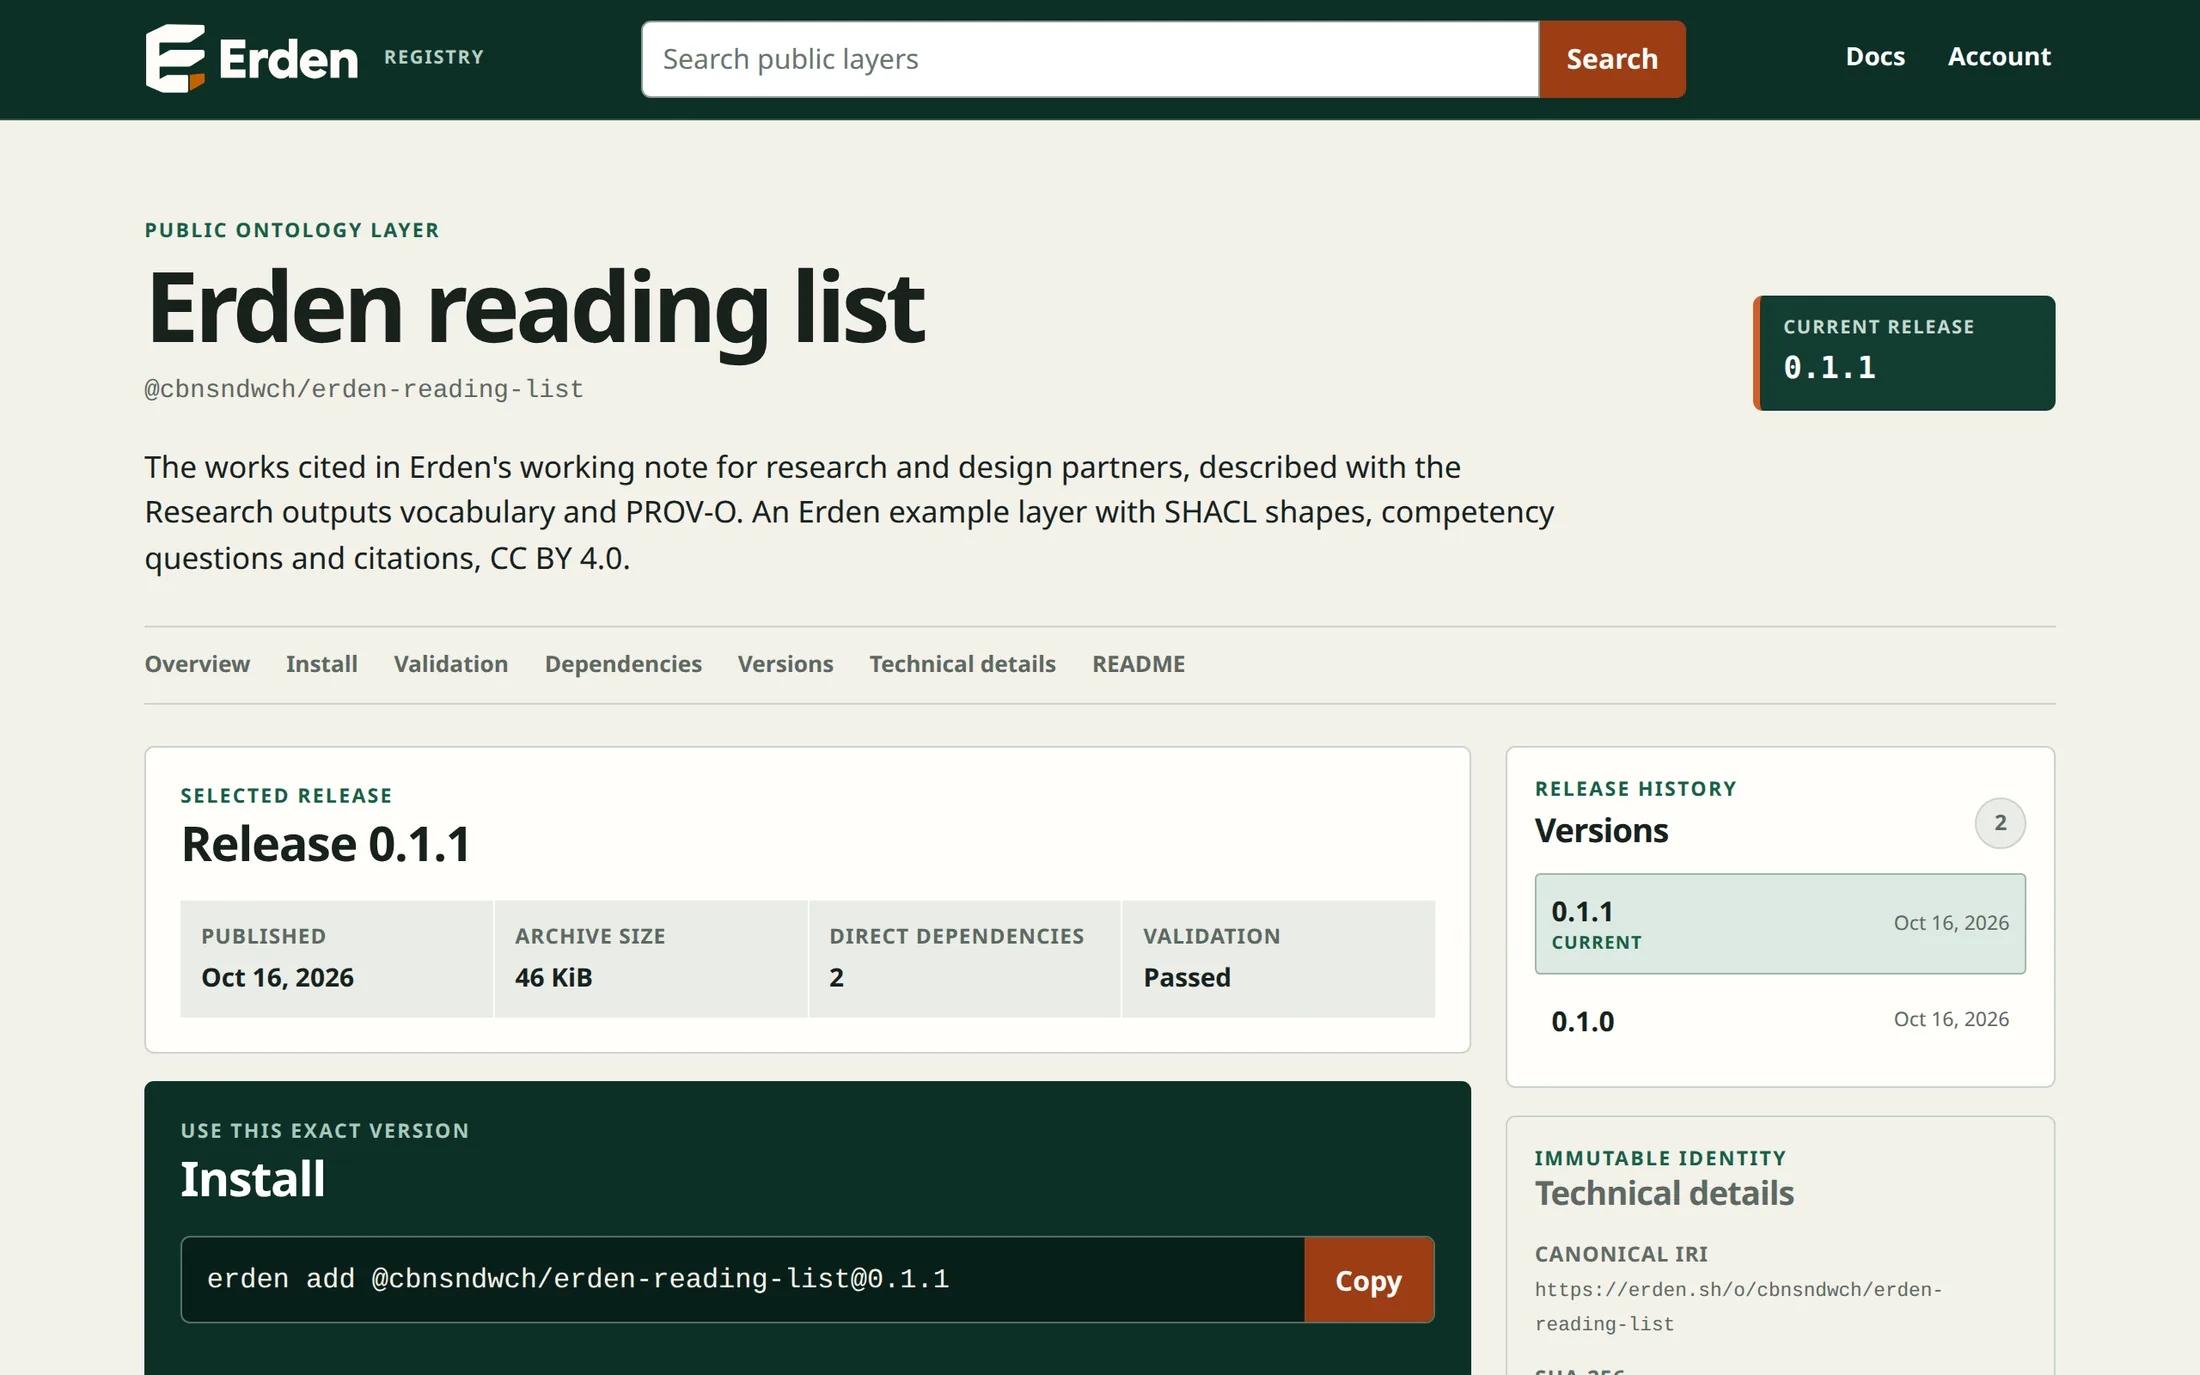
Erden treats an ontology as a package. It has a canonical identity, a SemVer history, explicit dependencies on other layers, a content digest, and a validation report. You publish it, other people resolve it, and the claims inside it carry the evidence that backs them.
What's There
- A publication pipeline. Packages upload as a single authenticated archive, stream straight into private object storage under backpressure, and get picked up by a server-owned worker. PostgreSQL owns the leases, fences, retry budgets, and the atomic release transition, so multiple replicas can race without corrupting a release.
- A registry. Anonymous discovery over canonical JSON routes: search current heads, walk a layer's release history, resolve a canonical IRI, pin an exact version. Every read rechecks current authority on the way through.
- A reasoner, so the platform checks ontologies as well as storing them.
- A package format (
application/vnd.erden.package.v1) with digest-addressed archives and bounded, declared dependencies. - An operational posture that assumes the host is not trusted. Dual-origin dispatch, secrets read only from files, a read-only root filesystem, a non-root UID, liveness separated from readiness, and logs that never carry identities, paths, headers, bodies, or stacks.
Why I'm Building It
I've spent the last few years watching agents and LLM tooling get dramatically better at doing things and barely better at remembering them. Every engagement starts by re-explaining the same context. Every new hire rebuilds the same mental model from scratch. The industry's answer so far has mostly been bigger context windows, which postpones the problem.
A maintained, versioned, verifiable ontology is the other answer. It's harder and less glamorous, and I think it's the one that compounds.
The evidence-backed part is the piece I care most about. A claim in a knowledge graph is worth very little if you can't trace where it came from. Provenance is the reason to trust the graph at all, so it belongs in the format from the start.
Status
In active development. The CLI and local toolchain are open source on GitHub under Apache 2.0. The hosted registry is invite-only for now, for design partners and researchers.
The shape I'm working toward is a central registry with distributed tooling: the last mile in the hands of whoever is doing the work, and the aggregation in the middle.
If this is a problem you actually have, I'd like to hear about it. erden.sh has a call for research partners and a contact form, and that's the most useful thing anyone could send me right now.
Tech Stack
- TypeScript
- Node 24
- PostgreSQL
- S3-Compatible Storage
- React
- Turborepo
- Playwright
- Docker
Latest Updates
View allApplications open for research and design partners
erden.sh now has a landing page, a working note and an application form for the first partners on the hosted registry.The local tools are open source
The Erden CLI, package format, reasoner protocol and both engines are now on GitHub under Apache 2.0.What broke when I checked real ontologies
A dry run with real domain models exposed the limits of the local tools. The CLI now reads more formats, explains itself better and runs on more platforms.Dependencies, a lockfile and offline checks
Erden projects can now depend on other ontologies, pinned in a deterministic lockfile and checked with no network access.erden check runs on your machine
The first working piece of Erden is a local CLI that validates an ontology project with a pinned, bundled reasoner.